Data Engineering2024-2025
Iliad Platform
Enterprise analytics platform centralizing 5 data sources for the educational management of the Wild Code School.
PrefectDBTDuckDBMongoDBAngularFlaskKafkaRedisDocker
Context & Objectives
Iliad Platform is an enterprise analytics application designed to centralize and leverage the Wild Code School's educational data. It provides a consolidated view of KPIs for data-driven management of the training programs.
Issues addressed:
- Trainers: No real-time visibility into learners' progress and satisfaction
- Educational managers: Late detection of problematic quests and of students at risk of dropping out
- Management: No consolidated metrics for strategic decisions
Key features:
- Tracking of Odyssey quest progress (progression, completion rate)
- Analysis of learners' ratings and reviews on each quest
- Certification pass rates by team and trainer
- Trainers' weekly feedback (Notion)
- Centralization of issues reported via Slack
- Satisfaction metrics (NPS, surveys)
Use cases:
1. Educational leads — Identify quests that need adjustments
2. Trainers — Follow feedback and continuously improve sessions
3. Management — Consolidated KPIs for strategic decisions
5
Integrated sources
8
Fact tables
9
Dimension tables
3
Use cases
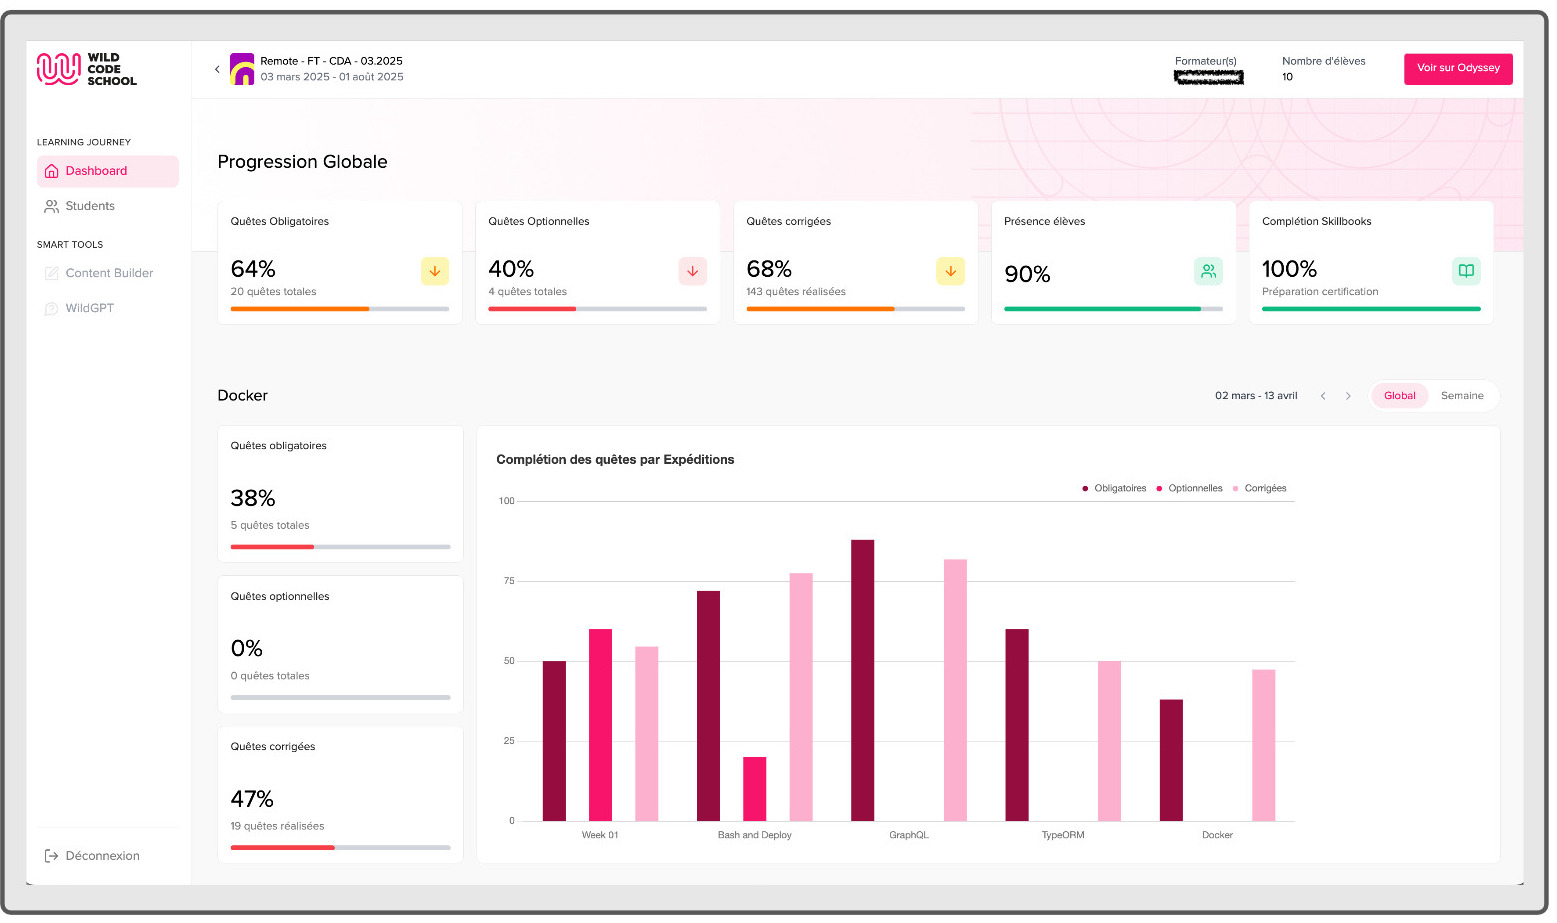
Main dashboard: real-time KPIs (completion, attendance, certifications) and charts by expedition
Data Architecture
Star schema data model optimized for OLAP analysis, with a clear separation between dimensions and facts.
Dimension tables:
- dim_expedition — Information on expeditions and learning paths
- dim_quests — Quest details and difficulty levels
- dim_crews — Teams and organization
- dim_users — Users (learners, trainers)
- dim_surveys — Survey configuration
- dim_missions — Missions and objectives
- dim_async_cohort — Asynchronous cohorts
- dim_async_courses — Asynchronous courses
- dim_survey_questions — Survey questions
Fact tables:
- fact_adventures — Quest progress
- fact_journeys — Learning paths and achievements
- fact_certif — Certification results
- fact_surveys_response — Survey responses and evaluations
- fact_absence — Absence tracking
- fact_corrections — Corrections and comments
- fact_completions — Completion rates
- fact_async_progressions — Asynchronous progress
Hybrid storage:
- DuckDB/MotherDuck — OLAP analysis, complex analytical queries
- MongoDB — Unstructured data (Slack, Notion)
- Redis — Cache and session management
- PostgreSQL — Odyssey source (raw data)
Star
Schema
DuckDB
Analytics database
Redis
Cache
MotherDuck
Cloud
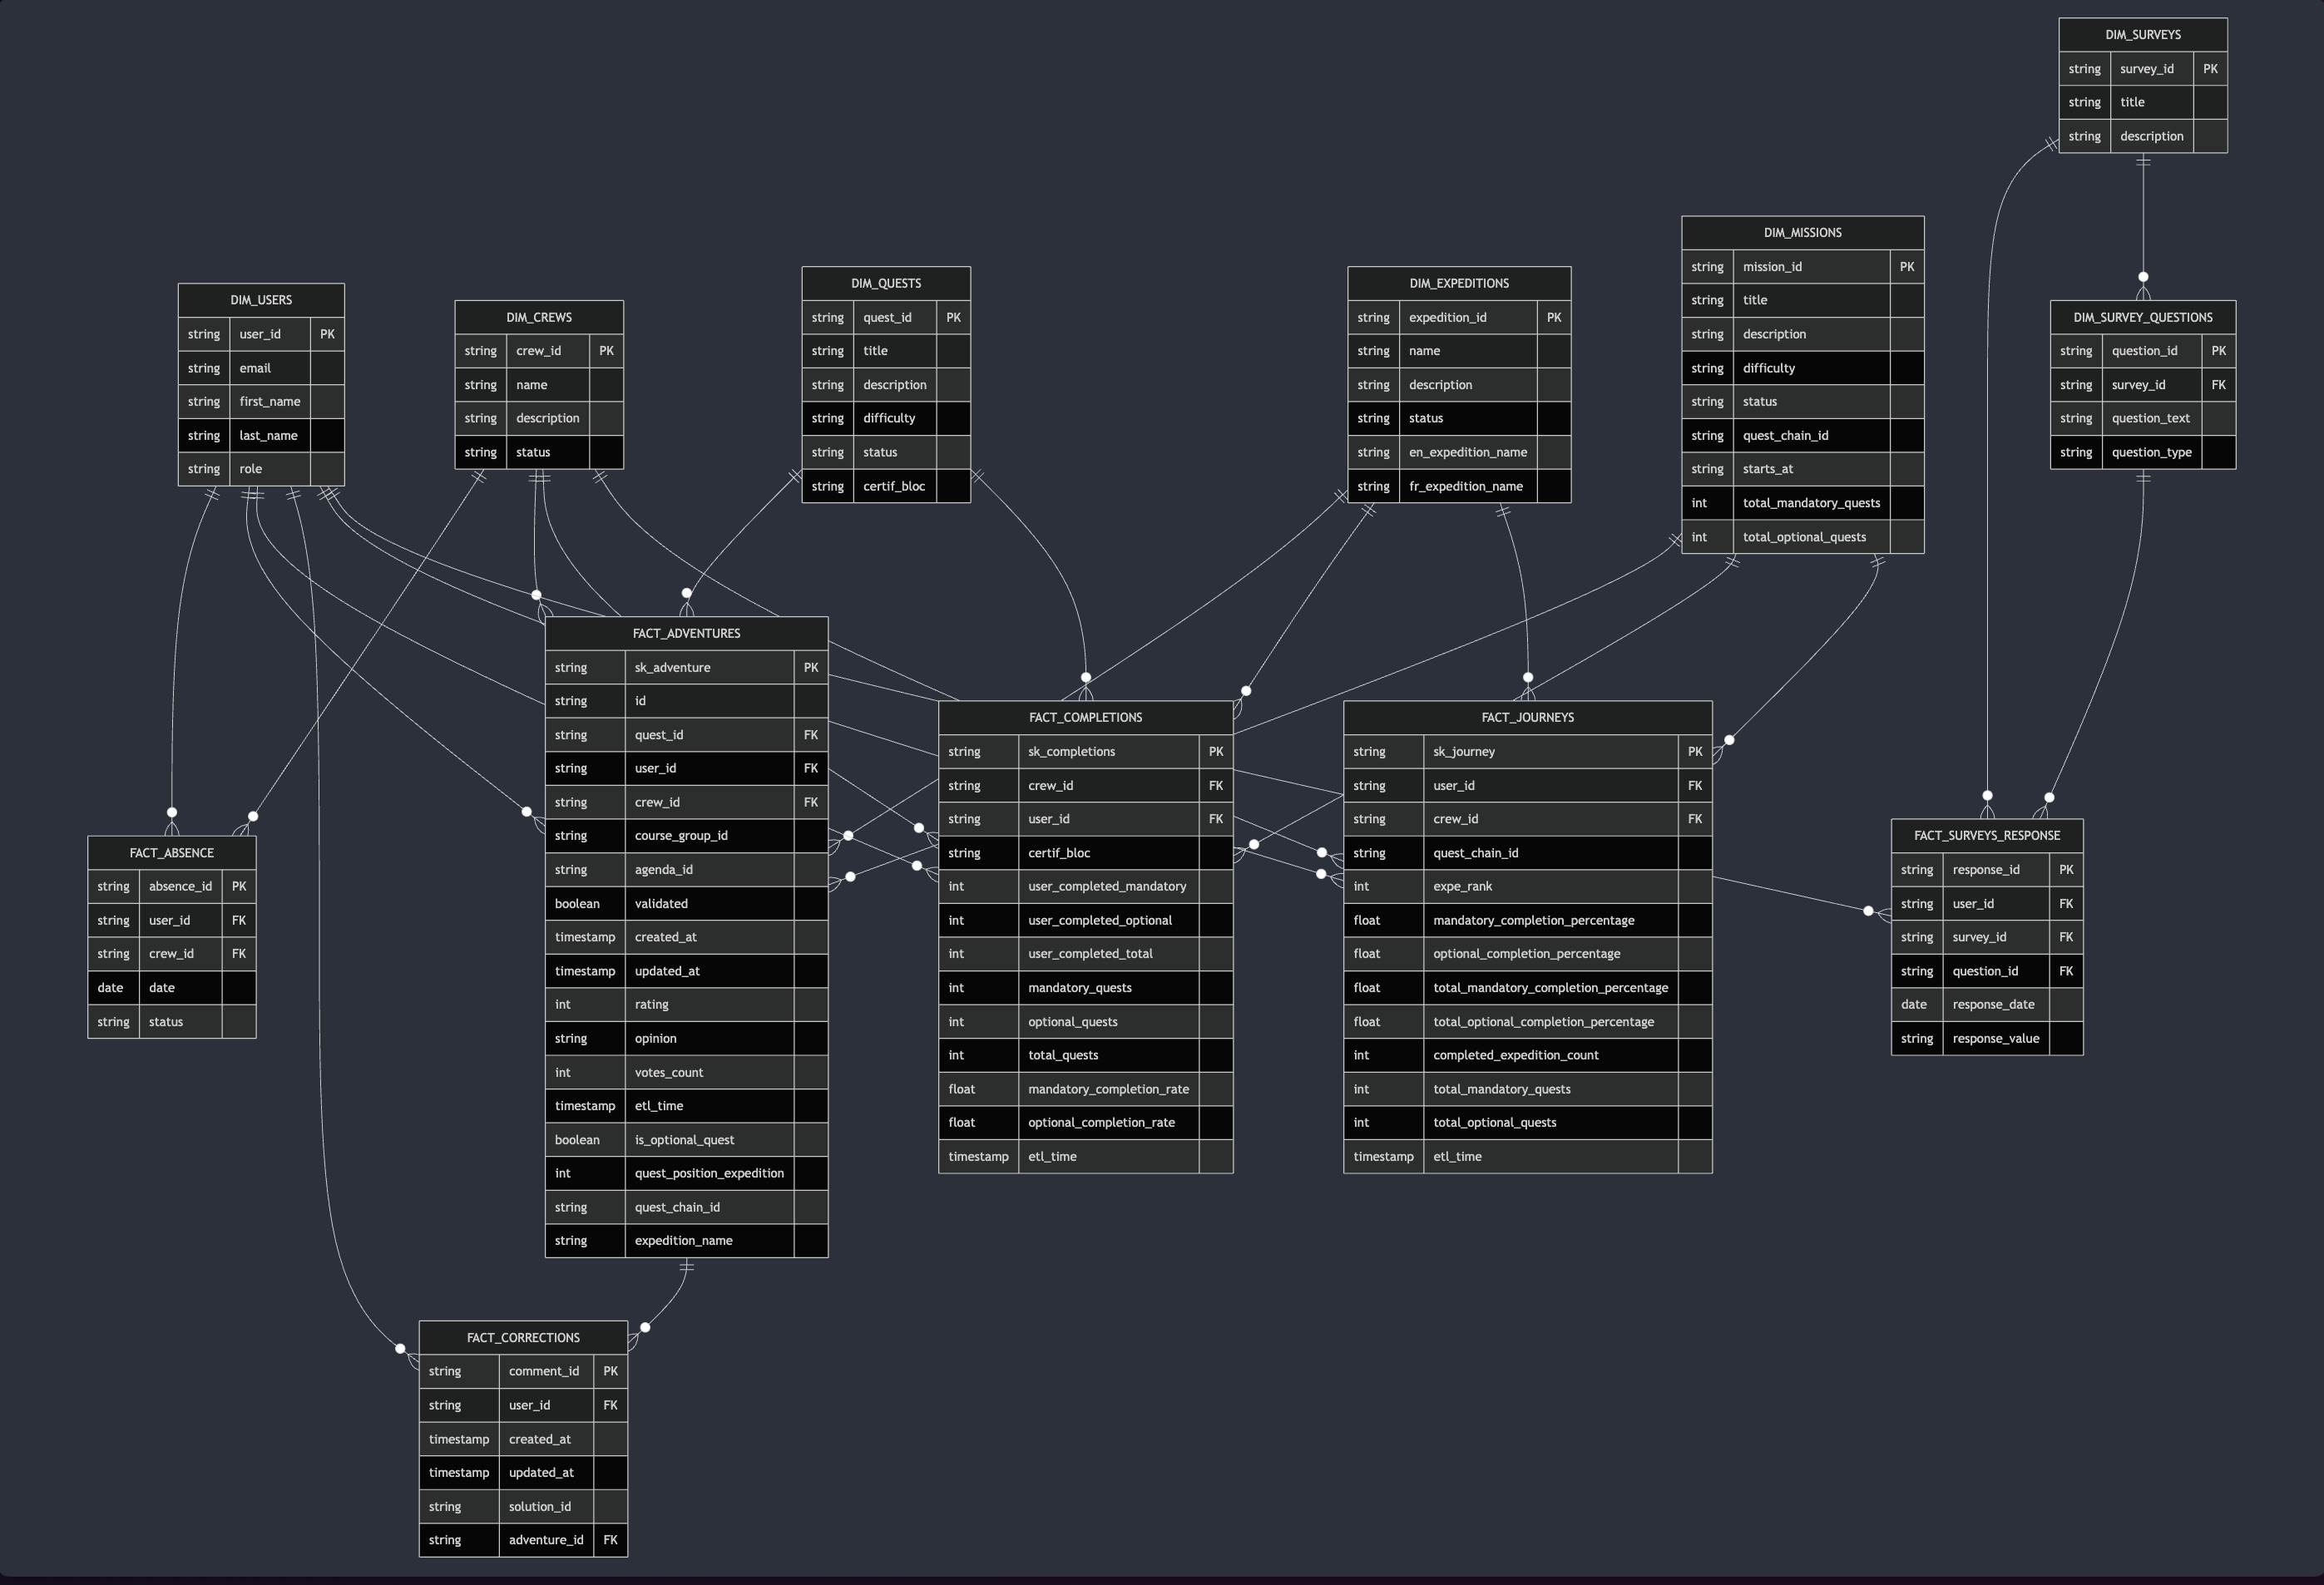
Star schema: 9 dimension tables, 8 fact tables
Integrations & Pipelines
5 heterogeneous data sources integrated through robust, orchestrated ETL pipelines.
Odyssey pipeline (PostgreSQL → DuckDB):
- Extraction of learner progress data
- DBT transformations for the analytical model
- Automatic sync to MotherDuck (cloud)
- Completion metrics and pass rates
Slack integration:
- Automatic capture of messages and threads
- Tracking of reported issues and resolutions
- Bot commands (/history, /help, /stats)
- Decoupled architecture with NATS JetStream
Notion integration:
- Two-way sync of weekly feedback
- Redis cache for optimal performance
- Automatic change detection
HubSpot integration:
- CRM sync (contacts, companies, tickets)
- Import of survey responses
- Export of insights to the CRM
Certifications pipeline (Google Drive):
- Extraction of results from Google Drive
- Smart user matching
- Tracking of pass rates by trainer/team
5
Sources
DBT
ETL
NATS
Messaging
Real time
Sync
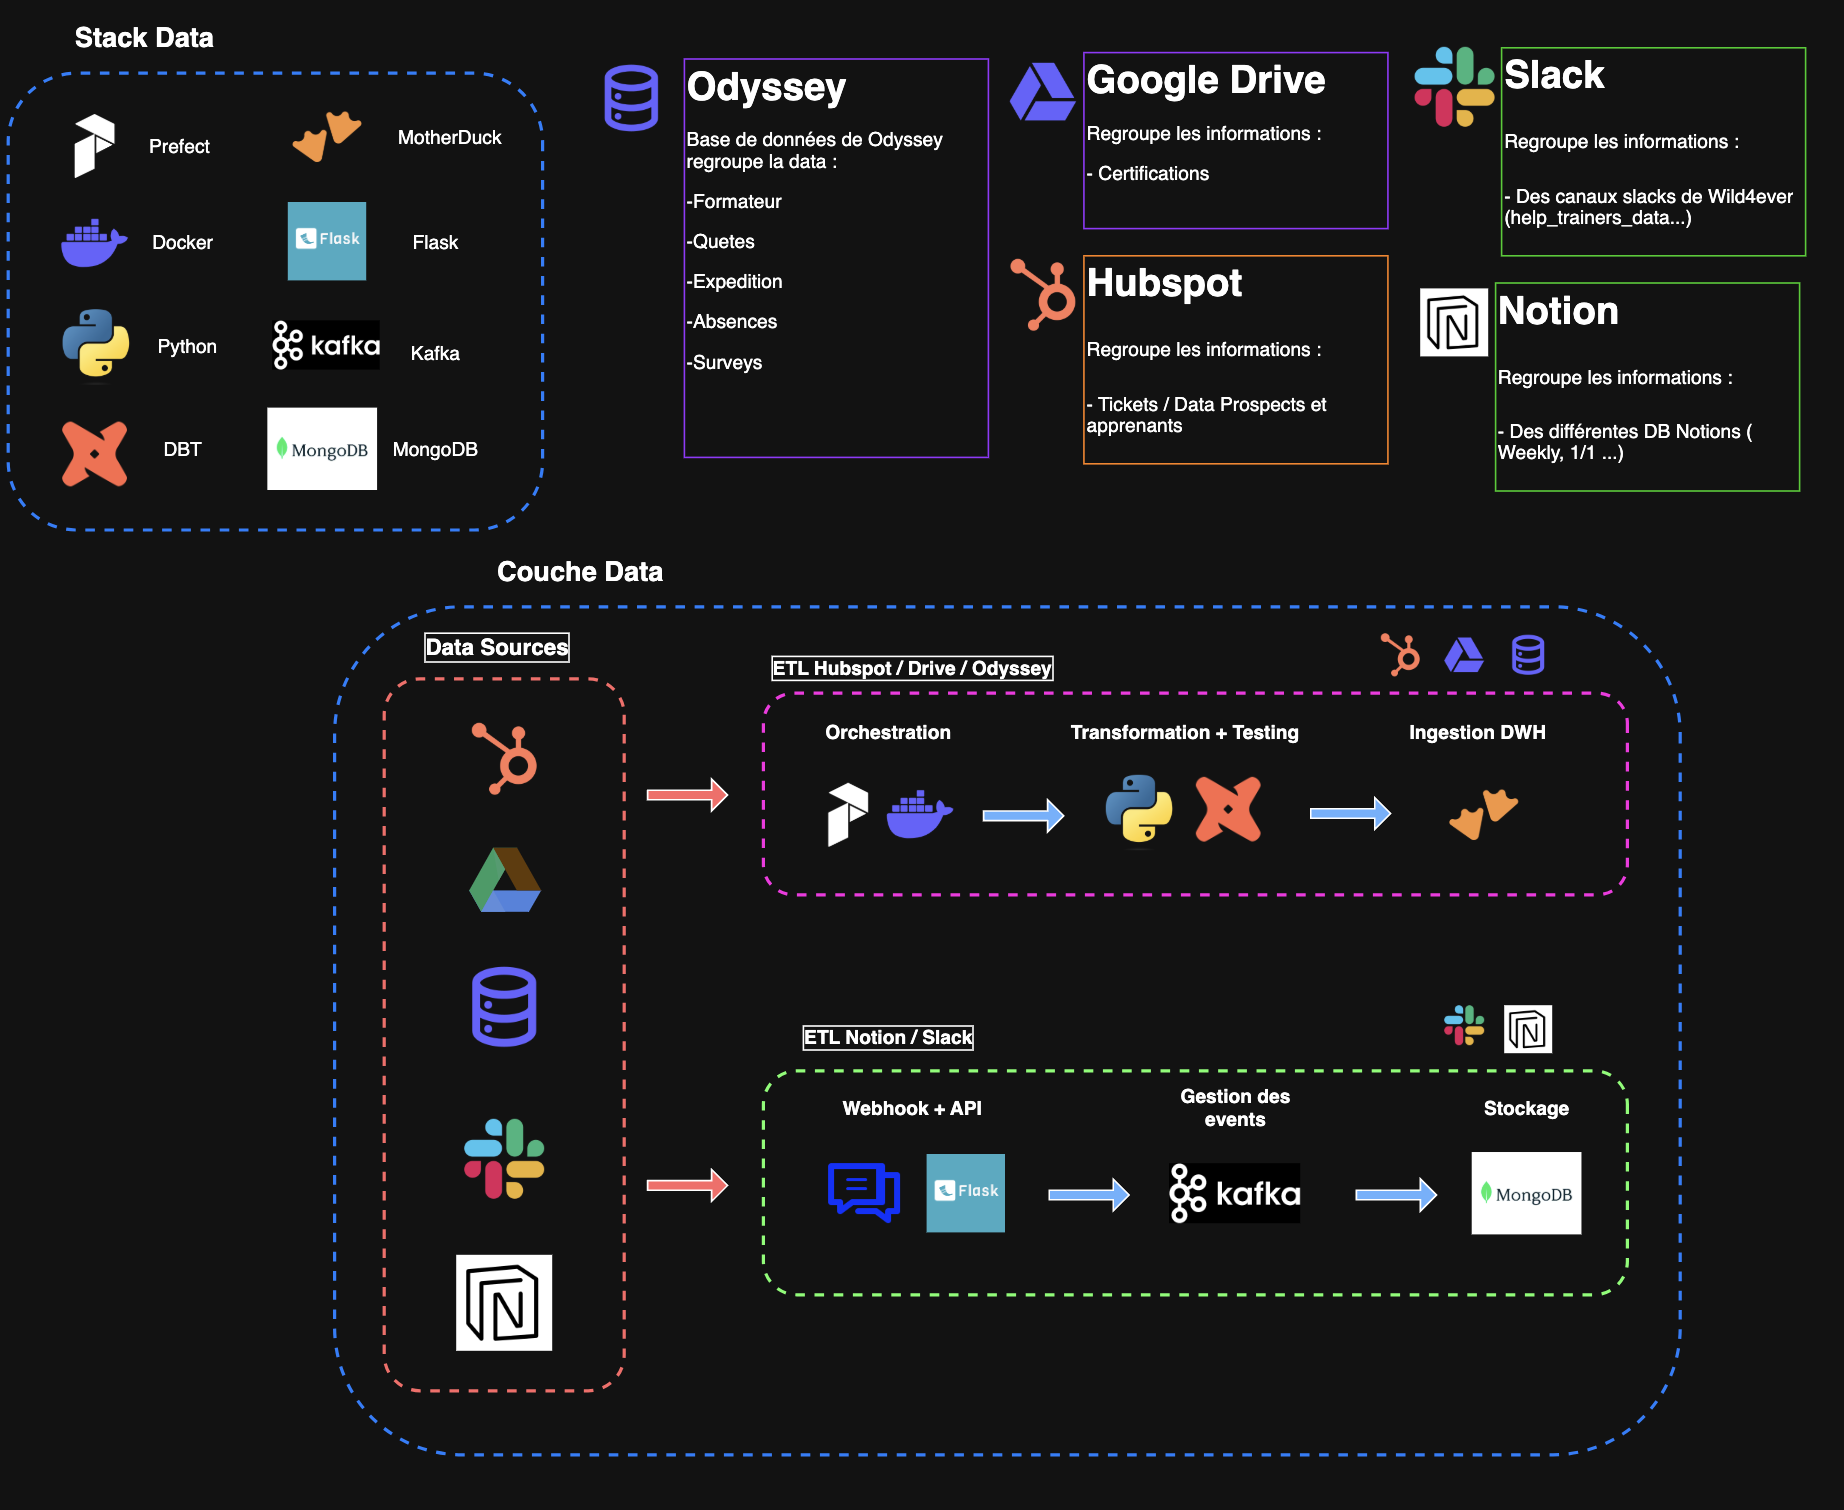
Data architecture: 5 sources (HubSpot, Google Drive, Odyssey, Slack, Notion), Prefect/DBT ETL to MotherDuck, Slack/Notion events through Kafka to MongoDB
Tech Stack
Modern full-stack architecture with frontend/backend separation and containerized infrastructure.
Frontend (Angular 18+):
- TypeScript 5.4+ with a modular architecture
- Tailwind CSS + Angular Material for styling
- Chart.js with ng2-charts for visualizations
- RxJS for reactive state management
- Smart search algorithm (context-aware)
Backend (Python/Flask):
- REST API with JWT authentication + refresh tokens
- RBAC (Role-Based Access Control)
- Redis cache with smart invalidation
- Input validation and security
Data Engineering:
- DBT for transformations (dev/prod targets)
- Prefect for workflow orchestration
- Local DuckDB / MotherDuck cloud
- Kafka/NATS for asynchronous messaging
Languages used:
- Python 3.8+ (backend, ETL, orchestration)
- TypeScript 5.4+ (Angular frontend)
- SQL (DBT models)
Infrastructure:
- Docker + multi-service Docker Compose
- Automated GitHub Actions CI/CD
- Nginx reverse proxy
- Let's Encrypt SSL with auto-renewal
Angular 18
Frontend
Flask
Backend
3
Languages
8+
Services
1 / 2
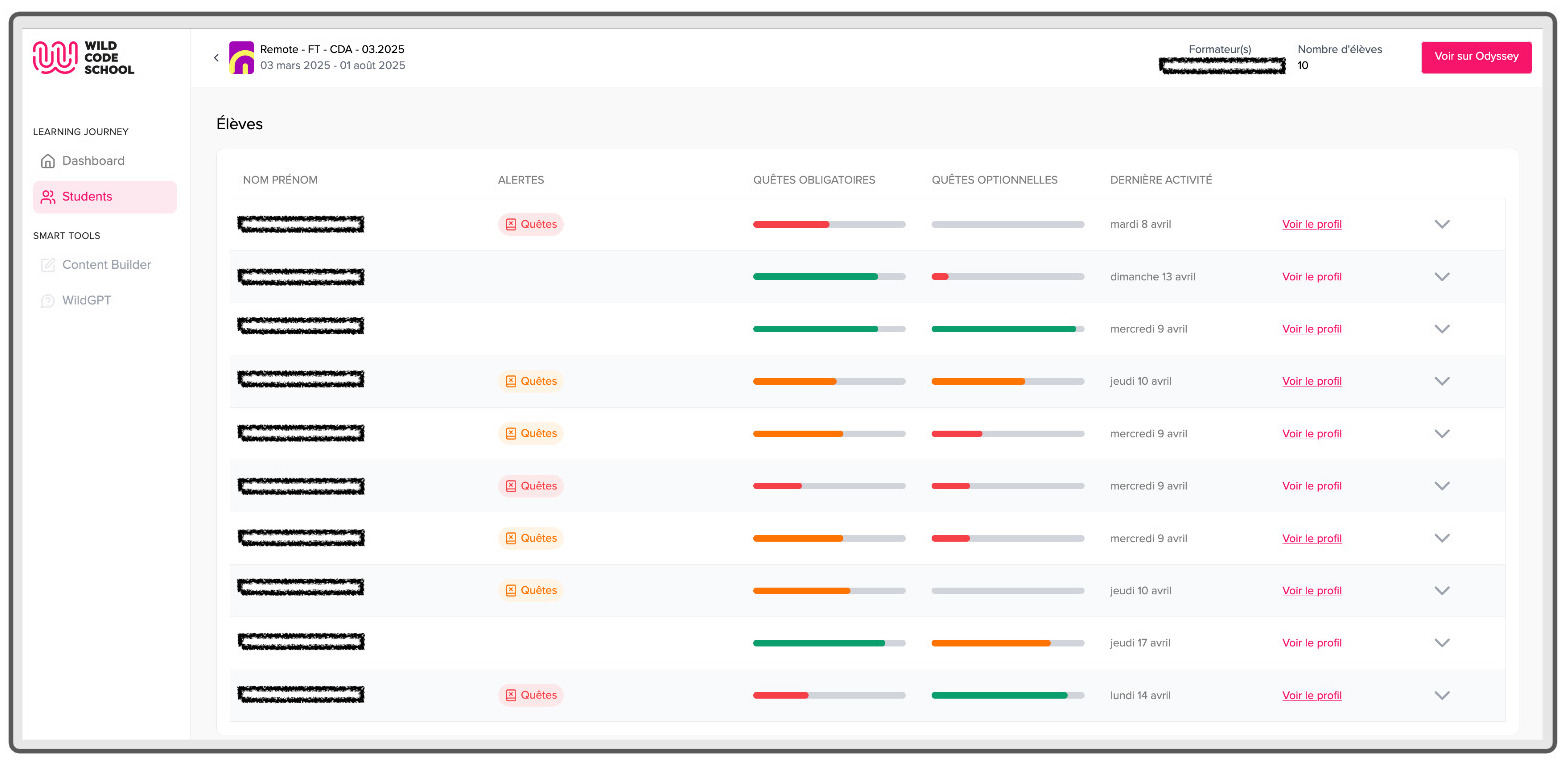
Students view: alerts, required/optional quest progress, last activity
Orchestration & DevOps
Production infrastructure with Prefect orchestration, automated CI/CD and built-in monitoring.
Prefect orchestration:
- Microservices API (port 8000) for manual triggering
- Freshness checks on DBT sources
- Management of deployments and flow IDs
- Endpoints: /health, /run/<service>
- Run monitoring and recovery on errors
GitHub Actions CI/CD:
- Automated pipeline: lint, tests, build, deployment
- Zero-downtime deployments
- Multi-environment management (dev, staging, prod)
- Automatic SSL with Let's Encrypt + cron renewal
Docker services:
- Frontend (Nginx + static Angular)
- Backend API (Flask)
- MongoDB (users, Slack messages)
- Redis (cache)
- Prefect (orchestration)
- NATS (message broker)
- Certbot (SSL)
Advanced features:
- Context-aware smart search (dates, names, places)
- JWT with automatic refresh
- Cache with statistics and health monitoring
- Structured logs and alerts
Prefect
Workflows
GitHub Actions
CI/CD
8+
Containers
Auto-renew
SSL